Revenue sooner
GPU capacity online in weeks, not months. Pre-integrated racks and parallel commissioning turn white space into earning capacity faster.
Your GPUs earn nothing until they’re in production. We get them there faster and keep them running.
One accountable team from white-space to runtime: integrate, power up, validate and run high-density GPU capacity, trusted by Microsoft to build and support scale datacenters worldwide.
Proven with Microsoft Azure NVIDIA Supermicro Lambda CoreWeave
ISO/IEC 42001 · ISO 27001 · SOC 2
GPU capacity online in weeks, not months. Pre-integrated racks and parallel commissioning turn white space into earning capacity faster.
One failed node can stall an entire run. Burn-in catches weak hardware before jobs start, and fast node recovery keeps more GPU hours productive.
Your customers feel every slowdown. 24×7 monitoring, rolling maintenance and fast remediation protect uptime, latency and your SLAs.
Build-out, validation and 24×7 operations under one team. One contract, one escalation path, from first rack to every refresh.
Try us on one fixed-scope engagement. See the results, then scale to full lifecycle support.
From white space to capacity
Every GPU watched, every hour
Move to the next GPU generation without downtime
What it costs to run GPUs without a professional host management team
419 interruptions in 54 days on a 16K-GPU H100 cluster
Hardware faults that need hands-on diagnosis and RMA
And 54% cost more than $100K
Most from skipped or flawed procedures
With better management and processes
Density growth makes it worse, not better
Sources: Meta, “The Llama 3 Herd of Models” (2024); Uptime Institute Annual Outage Analysis 2025.
Aptly’s 24×7 host management team catches failures early and returns nodes to service fast.
Get a buildout readiness reviewAptly’s AI Data Center services provides full-spectrum lifecycle management: From design validation to operation, at scale.
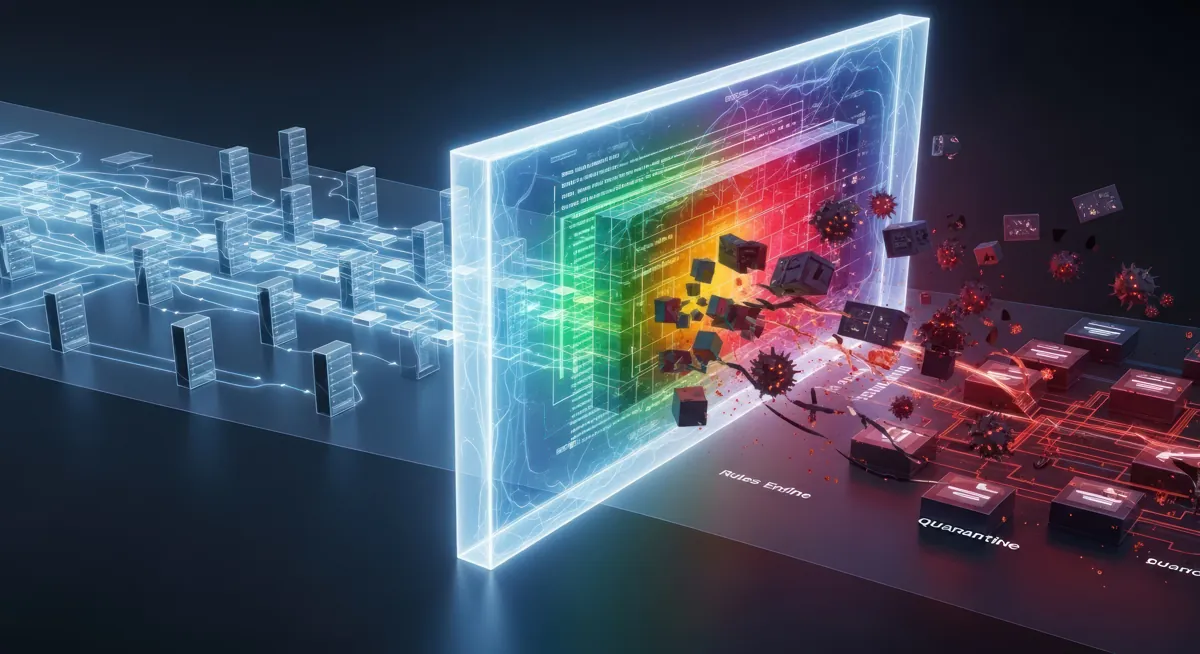
AI-Assisted Operations → Governed Remediation → Human Expertise
Aptly uses AI to detect, diagnose, and automatically remediate approved, repeatable issues, while 24×7 Aptly engineers handle complex and high-impact incidents. Customers define what AI can automate, keeping critical actions governed, auditable, and under human control.
Delivered GPU and compute clusters across Azure regions worldwide.
Joint delivery of pre-assembled racks and factory-burned solutions, reducing customer deployment time by up to 40%.
Aptly handles network link-down recovery, node availability, lifecycle upgrades, and uptime management.
Standardized playbooks and automation pipelines reduce deployment timelines from months to weeks.
Deep field experience across HPE, Dell, Lambda, CoreWeave, Nebius, and NVIDIA reference architectures.
Dedicated teams across the U.S., Europe, India, and nearshore centers to ensure 24×7 delivery and coverage.
AI data center buildout services cover the design, integration, deployment, validation, and commissioning required to bring high-performance AI data center infrastructure into production. Aptly supports the lifecycle from AI data center design and rack integration through networking, power, cooling, cluster validation, commissioning, and ongoing infrastructure support.
AI infrastructure deployment involves integrating GPU compute, high-speed networking, power distribution, cooling, firmware, operating systems, and monitoring into a production-ready environment. Aptly’s AI infrastructure integration approach includes: rack energization, configuration, AI data center networking, infrastructure validation, and readiness testing to help organizations deploy reliable GPU infrastructure at scale.
Aptly supports end-to-end AI cluster deployment, from GPU rack integration and network configuration to cluster validation and burn-in testing. GPU nodes and interconnects are stress-tested across thermal, PCIe, and NVLink paths, with performance benchmarking and reliability validation performed before production readiness and acceptance sign-off.
Aptly designs and deploys high-performance AI data center networking for large-scale GPU clusters, including InfiniBand, RoCE Ethernet, and NVLink interconnects. Network validation includes topology checks, port testing, redundancy and failover testing, and diagnostics to help maintain the low-latency, high-bandwidth connectivity required by distributed AI workloads.
Aptly evaluates power distribution, cooling capacity, rack density, airflow, and thermal management as part of the AI infrastructure buildout process. For high-density GPU infrastructure, this includes validating PDU capacity, thermal zoning, airflow requirements, and infrastructure readiness, including liquid cooling requirements where applicable, to support reliable AI infrastructure scaling.
Yes. Aptly provides ongoing AI data center operations after infrastructure deployment and commissioning, helping organizations operate and maintain production AI environments at scale. Our managed data center operations services include 24×7 data center monitoring, incident management, smart hands support, infrastructure troubleshooting, preventive maintenance, GPU and network support, spares and RMA coordination, capacity management, and operational optimization. This provides continuous support for GPU infrastructure, high-density AI clusters, and other mission-critical AI data center infrastructure.
AI data center buildout costs vary based on GPU cluster size, networking, rack density, power, cooling, and deployment requirements. Contact Aptly Technology directly for a customized AI data center buildout cost estimate.
Yes. Aptly can deploy, validate, commission, and manage AI data center infrastructure throughout its lifecycle. Services include GPU infrastructure integration, rack deployment, AI networking, cluster validation, 24×7 monitoring, incident response, hardware and firmware support, and ongoing infrastructure optimization.
Yes. Aptly helps enterprises build data centers for AI by integrating and deploying GPU infrastructure, high-speed networking, power and cooling systems, and AI clusters. Services span design validation, rack deployment, commissioning, infrastructure validation, and ongoing 24×7 support.
Built for reliability, optimized for performance, and supported every hour of every day.
Book an AI Infrastructure Buildout & Readiness CallYou’re asking about
From the page. You can change it in the form.
What happens next
Tell us what you need and our team will get back to you.